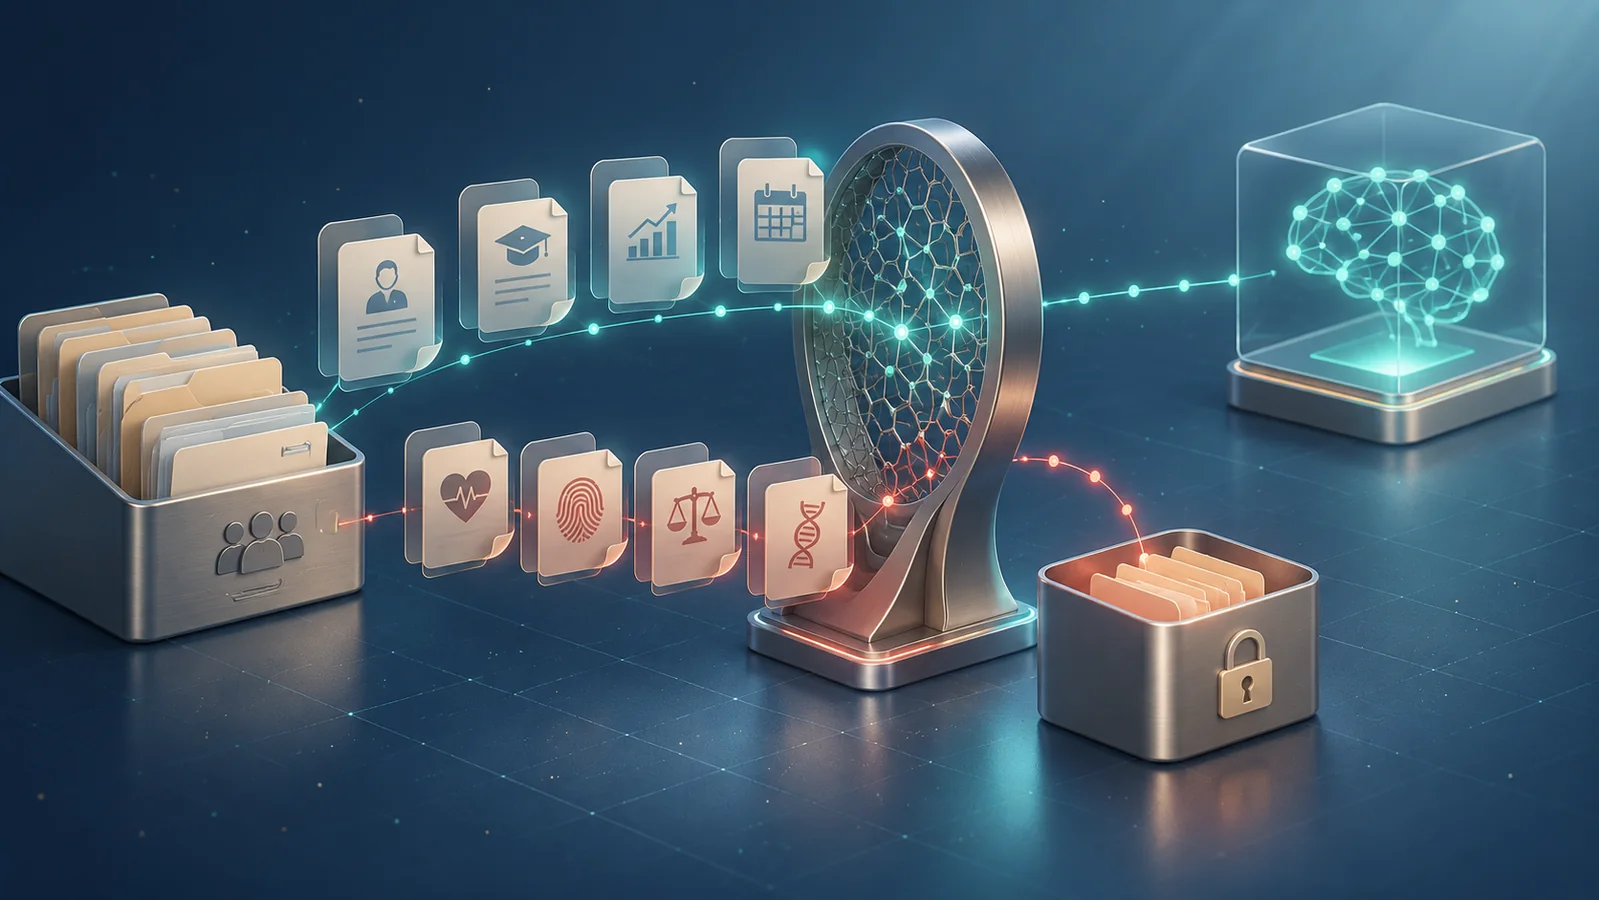
Organisations are investing heavily in AI for recruitment, talent management and workforce planning. But not all information held by HR departments is suitable for these uses. Which categories should be excluded from training or inference datasets under GDPR requirements and in light of discrimination risks and technical threats? This article sets out the legal framework, identifies data to exclude, examines technical threats and outlines governance measures for CIOs, CISOs, DPOs and executives seeking to use AI without undermining compliance or employee trust.
Introduction
Imagine a multinational's AI department deciding to feed its internal recommendation model with the full medical records of its 12,000 employees. Within weeks, the system identifies correlations between chronic illnesses and performance, generating mobility suggestions that, while seemingly relevant, expose every employee to a risk of illegal discrimination. A scandal erupts, data protection authorities launch an investigation, and the company sees its reputation tarnished and its legal budget skyrocket.
This scenario is not hypothetical: several recent incidents (e.g., health data leaks via a language model in 2022, sexist biases detected in a skills assessment tool) demonstrate that the temptation to use 'all' HR assets as raw material for AI can quickly become a costly blunder.
The challenge is twofold: complying with legal obligations (GDPR, Labour Code, European AI directives) and preserving the security and fairness of the models. To achieve this, one must first identify which data should be excluded a priori from any internal AI system, and then implement the necessary safeguards.
1 Legal and regulatory framework applicable to HR data
| Text | Main articles / requirements | Scope for AI |
|---|---|---|
| GDPR (EU) 2016/679 – Art. 9 | Prohibition of processing special categories of data unless there is an explicit legal basis (consent, legal obligations...) | Any sensitive data (health, racial origin, political opinions...) must be justified and often excluded from generic models |
| French Labour Code – L.1221-6 & L.1121-1 | Protection of employee privacy; limitation of processing to legitimate professional purposes only | The use of private information (e.g., health status) must be proportionate and documented |
| Decree No. 2021-1260 (IA Act – French draft) | Obligation to assess discriminatory risks of high-risk automated systems, including HR AI | Requirement for an impact analysis prior to model training |
| CNIL – Guide 'AI and personal data best practices' (2023) | Recommendations on minimisation, anonymisation, and access control | Explicitly indicates which categories of HR data must be prohibited or pseudonymised |
| ISO/IEC 27701 (Privacy Information Management) | Governance framework for personal information privacy | Provides documentation and access control requirements for AI projects |
In summary: the processing of any data falling under Article 9 of the GDPR or categories protected by labour law must be justified, time-limited, and subject to reinforced governance. The absence of a legal basis constitutes sufficient grounds to exclude such data from internal AI systems.
2 Typology of HR data to be systematically prohibited
| Category | Concrete example | Why ban it? |
|---|---|---|
| Health data (diagnostics, treatments, medical records) | Sick leave certificate, preventive check-up results | Art. 9 GDPR; risk of discrimination and stigmatisation; inversion model may reveal an individual's health status |
| Biometric information (fingerprints, facial recognition, voice data) | ID photo for access badge, fingerprint for time tracking | Art. 9 GDPR; high identifiability, targeting via "spoofing" attacks |
| Genetic data | DNA analysis performed as part of a voluntary health programme | Art. 9; extreme sensitivity, risk of re-identification even after aggregation |
| Political / trade union opinions | Declaration of political party affiliation, participation in a strike | Art. 9; enhanced protection, risk of professional retaliation |
| Religious or philosophical beliefs | Practice of fasting during Ramadan, requests for faith-related accommodations | Art. 9; potential discrimination in promotion or mobility decisions |
| Sexual orientation & gender identity | Declaration of transition, information regarding personal life | Art. 9; stigmatisation and gender bias in employment recommendations |
| Information relating to family status (marital status, number of children) when used for automated decision-making | Use of the number of children to adjust salary or working hours | May lead to indirect discrimination (e.g., family burden) |
| Disciplinary sanction data (warnings, suspensions, internal legal proceedings) | Complete history of an employee's disciplinary sanctions | Risk of negative bias in performance evaluation and violation of the principle of proportionality |
| Fine-grained geolocation information (real-time GPS tracking) | Location data originating from mobile time-tracking applications | Intrusion into private life; requirement for explicit consent is rarely justifiable |
Key takeaway: any data classified as a 'special category' under GDPR or likely to create a power imbalance must be excluded a priori from training and inference datasets.
3 Technical risks associated with feeding AI with this data
3.1 Leaks and re-identification
Even when data is aggregated, generative models (LLM, diffusion) can be exploited via membership inference or data reconstruction attacks: an adversary queries the model with targeted prompts to retrieve sensitive information that was not explicitly stored.
3.2 Discriminatory biases
Variables such as age, gender, or ethnicity are often correlated with other attributes (e.g., salary level). If these fields are retained in the training set, the model may learn biased associations and reproduce or amplify existing discrimination.
3.3 Model inversion attacks
An attacker with limited access to the AI system's API could partially reconstruct original inputs (e.g., medical records) by analysing gradients or probabilistic responses, thereby compromising employee confidentiality.
3.4 Regulatory non-compliance and sanctions
Failure to comply with the data minimisation obligation (GDPR Art. 5(1)(c)) exposes the company to fines of up to 4% of total worldwide annual turnover or €20M, excluding costs associated with corrective actions and loss of trust.
4 Legitimate use cases: where is the scope actually open?
| Use case | Generally accepted data | Restrictions |
|---|---|---|
| Automated recruitment (CV screening) | Professional background, declared skills, qualifications | Exclude health data, political opinions, and family information. Anonymise names and addresses from the pre-selection phase. |
| Talent management & planning | Project history, performance evaluations (objective), availability | Mask the exact reasons for any performance gaps (e.g., health issues); anonymised aggregations for trend analysis. |
| Schedule optimisation | Working hours, shift preferences, legal constraints (rest periods) | Do not exploit fine-grained GPS tracking data or activities outside of contractual hours. |
| Organisational climate analysis | Anonymous surveys, satisfaction scores | Ensure encryption and non-traceability of individual responses; avoid any correlation with the respondent's identity. |
Key principle: each use case must be preceded by a Privacy Impact Assessment (PIA) to validate that the data used is proportionate, necessary, and correctly secured.
5 Secure architecture for HR data processing

Read the diagram notation
flowchart TD
    A[Sources RH] --> B{Data Lake sécurisé}
    B --> C["Ingestion (ETL) avec filtrage"]
    C --> D[Anonymisation / Pseudonymisation]
    D --> E["Data Vault (chiffrement au repos)"]
    E --> F["Environnement d’entraînement IA (sandbox)"]
    F --> G[Modèle entraîné]
    G --> H[Déploiement en production]
    style B fill:#f9f,stroke:#333,stroke-width:2px
style D fill:#bbf,stroke:#333,stroke-width:2px- Controlled ingestion: ETL pipelines include a filtering step that automatically removes any column corresponding to prohibited categories (e.g., health_status, political_affiliation).
- Anonymisation / pseudonymisation: prior to storage, direct identifiers are replaced by UUIDs and sensitive attributes are aggregated or blurred using differential privacy techniques (controlled ε‑budget).
- Encryption at rest: all data vault tables use AES‑256 with key rotation managed by an HSM (Hardware Security Module).
- Training sandbox: the learning environment is isolated, with no external network access, to mitigate the risk of exfiltration via covert channels.
- Role-Based Access Control (RBAC): only authorised data scientists and the DPO can view the dataset metadata.
This architecture meets confidentiality, integrity, and traceability requirements while maintaining the flexibility required for AI experimentation.
6 HR Dataset Governance
| Item | Concrete Action | Owner |
|---|---|---|
| Source Inventory | Automated catalogue (CMDB) listing every table, field, and owner | CIO / Data Owner |
| Classification | Tagging based on sensitivity level (public, internal, sensitive, highly sensitive) | DPO |
| Pre-ingestion validation | Approval workflow including DPO + HR for each new dataset | AI Committee |
| Continuous audit | Quarterly scans using data loss prevention (DLP) tools to detect leaks of prohibited fields | CISO |
| Documentation of legal bases | Register describing the legal basis (consent, contractual obligation...) | Compliance Legal Counsel |
| Withdrawal and archiving | Automated deletion process after X months of inactivity or project completion | AI Officer |
A robust governance process enables the demonstration of compliance during a CNIL audit and limits operational risks.
7 Specific points of vigilance for AI models
7.1 Model Inversion & Membership Inference
- Symptom: the model returns overly precise responses when provided with a prompt containing very little information.
- Mitigation: apply differential privacy during training, limit output granularity (e.g., providing aggregated scores rather than individual probabilities).
7.2 Imbalanced Data Bias
- Symptom: model performance varies significantly based on the candidate's gender or age.
- Mitigation: resampling, class re-weighting, fairness audits (e.g., Equal Opportunity and Demographic Parity metrics).
7.3 Reliance on Outdated Data
- Symptom: the model recommends training courses that no longer align with current market skills.
- Mitigation: implementation of a periodic retraining pipeline with validation of source freshness (TTL).
7.4 API reverse-engineering risks
- Symptom: a malicious user retrieves model weights through multiple API calls.
- Mitigation: rate limiting, strong authentication, monitoring of abnormal access patterns.
8 Operational recommendations for decision-makers
| Priority | Action | Expected impact |
|---|---|---|
| 1. Define a 'data-exclusion' policy | Formally prohibit the processing of categories listed in section 2 within any HR AI project. | Legal compliance & reduction of discrimination risk. |
| 2. Establish an automated anonymisation pipeline | Use certified tools (e.g., Aircloak, ARX) for pseudonymisation prior to storage. | Data minimisation and protection against inference attacks. |
| 3. Implement systematic PIAs | Every new AI model must undergo a privacy impact assessment validated by the DPO. | Documentation of legal justification and visibility of residual risk. |
| 4. Apply differential privacy during training | Select an appropriate ε budget (e.g., 0.5–1) to ensure strong theoretical protection. | Limits an attacker's ability to reconstruct the original data. |
| 5. Regularly audit datasets | Quarterly scans using DLP + access log reviews. | Early detection of leaks or poor practices. |
| 6. Train AI and HR teams | Awareness programme on ethical and regulatory risks. | Adoption of a 'privacy-by-design' culture. |
| 7. Documenting the model lifecycle | Versioning of datasets, hyperparameters, and fairness metrics. | Traceability for internal and external audits. |
Operational conclusion
The introduction of artificial intelligence into the human resources function offers undeniable efficiency potential: reduction in recruitment time, improved visibility on