Generative language models (LLMs) are integrated into support, documentation, and decision-making systems. They can return obsolete procedures or procedures that conflict with the current official version. A fluent response can hide these discrepancies, putting regulatory compliance, operational security, and user trust at risk. RAG, content lifecycle management, and AI governance keep responses up to date. Decision-makers need a framework for establishing a reliable link between source data and AI-generated answers.
Introduction: when an AI's "truth" becomes obsolete
Imagine a bank call centre operator using a GPT-4 powered virtual assistant to verify the reporting procedure for a suspicious transaction. Within seconds, the assistant provides a detailed description: 'The client must be informed within 24 hours of detection and the file submitted to the compliance department via form X'. However, for the past three months, European regulations (revised PSD2) have mandated a 12-hour window and the use of the new form Y. The operator follows the incorrect recommendation, exposing the bank to sanctions and compromising its reputation.
This scenario illustrates two contemporary realities:
- The rapid dynamics of the regulatory and operational landscape – procedures often evolve several times a year.
- The way LLMs operate, relying on a frozen (or partially updated) training corpus and generating text 'based on what they have seen', without intrinsic temporal verification.
When an AI is tasked with retrieving business processes, the risk of contradictory documentation arises as soon as the model is not aligned with current official sources. The challenge, therefore, is to prevent the AI from presenting an obsolete procedure as a current truth while maintaining its advantage of natural interaction.
1. Origins of contradictions: why do LLMs display outdated content?
| Source | Description | Impact on generation |
|---|---|---|
| Static training corpus | Models are pre-trained on large volumes of text collected before a specific date (e.g., GPT-4: data up to September 2021). | No internal mechanism differentiates 'current procedure' vs 'previous version'. |
| Limited incremental updates | Fine-tuning or instruction tuning adds recent examples, but the volume remains marginal compared to the base corpus. | The probability of recent information being selected decreases as the size of the historical context increases. |
| Absence of temporal metadata | Tokens do not include 'validity date' attributes. | The model cannot filter by date without external assistance. |
| Insufficient prompting | The user does not specify the timeframe (e.g., 'procedure in effect as of 1 January 2024'). | The model responds based on its best guess, often based on the most frequent occurrence in the training data. |
| Retrieval system failure (RAG) | If the retrieval component does not refresh its indices, it returns obsolete documents. | The AI integrates these snippets as reliable sources. |
These factors combine to create an inertia effect: the generation tends to reproduce historical versions that remain predominant in the corpus, even if they are outdated.
2. Reference Architecture: From RAG to AI Governance
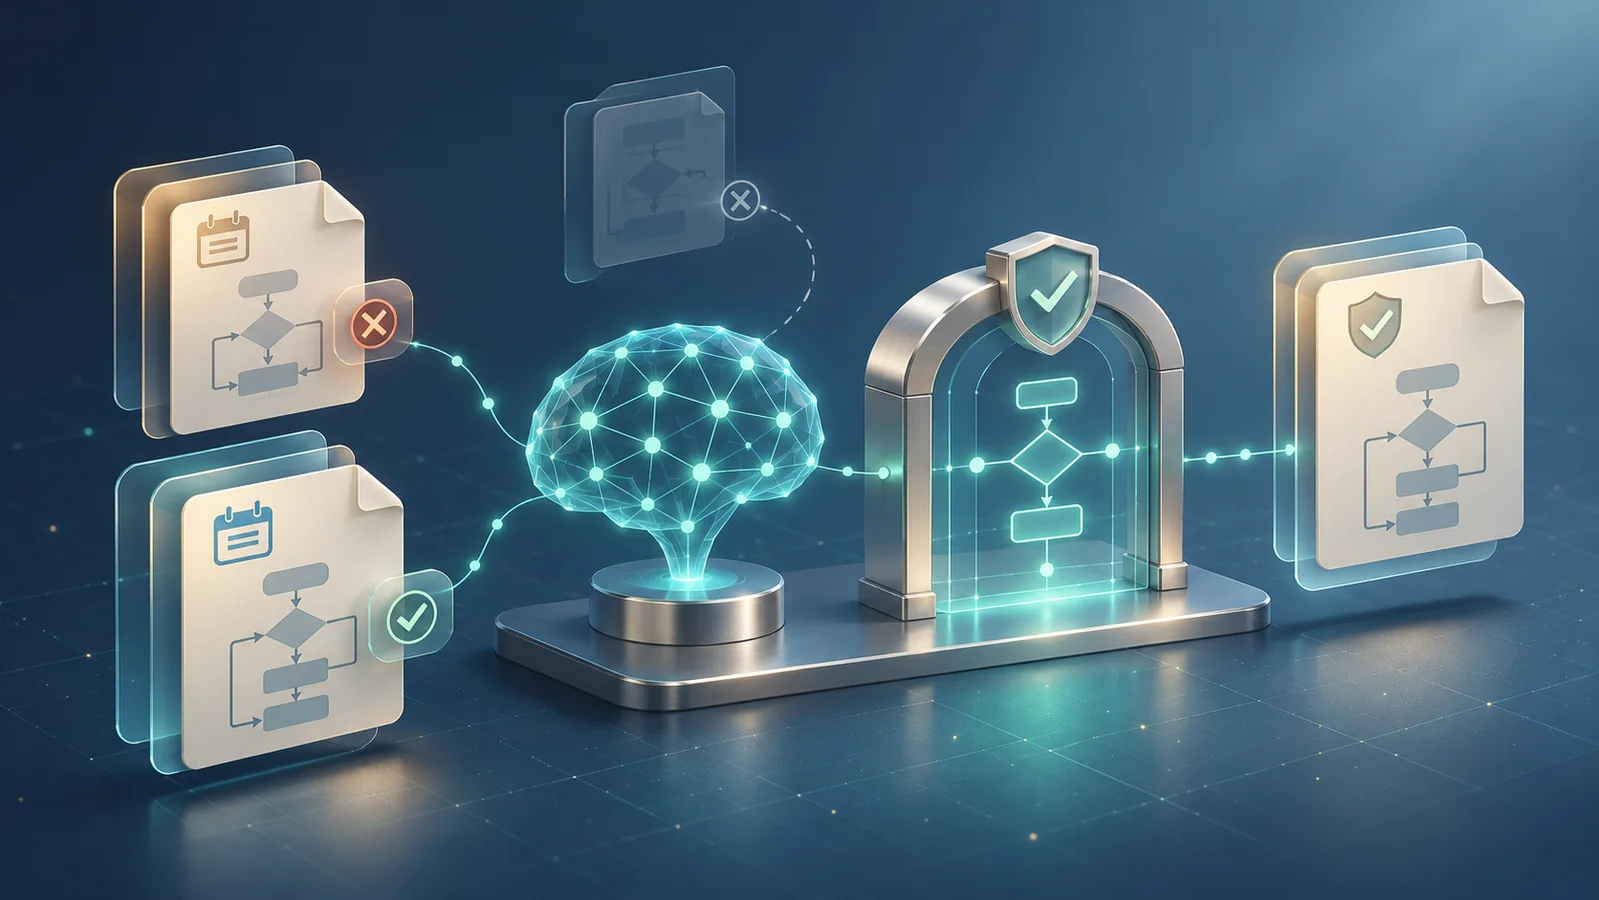
To ensure that the AI only returns current procedures, the model must be placed at the centre of a knowledge-oriented architecture:
+-------------------+      +----------------------+      +----------------------+
|   Source officielle (PDF, Wiki, API)  | → |   Indexation temporelle   | → |   Retrieval Service   |
+-------------------+      +----------------------+      +----------------------+
                                                            |
                                                            v
+-------------------+      +----------------------+      +----------------------+
|  Prompt Engineering Layer            | ← |   Knowledge Graph /    | ← |  Validation Engine   |
+-------------------+      |  Versioning Service   |      +----------------------+
                               ^                     ^
                               |                     |
                           +--------+          +----------+
                           | LLM (RAG) |←───────| Contextual|
                           +--------+          |  Filter   |
                                                +----------+
2.1 Temporal Indexing and Metadata
- Automated Ingestion: each official document (procedure, regulation, operating manual) is ingested via a dedicated CI/CD pipeline.
- Metadata: publication date, version, status (active, obsolete), functional domain.
- Vectorisation: content is transformed into embeddings (e.g. OpenAI text‑embedding‑ada‑002) and stored in a vector database (FAISS, Milvus) along with their metadata.
2.2 Retrieval Service (RAG)
The search engine relies on two filters:
- Temporal Filter – returns only documents where status = active as of the execution date.
- Relevance Score – combines vector similarity and freshness weight (e.g. score_total = α·sim + β·freshness).
2.3 Prompt Engineering & Contextual Filter
The prompt sent to the LLM explicitly includes:
[CONTEXT] Vous êtes un assistant d’entreprise. Toutes les réponses doivent se baser sur les procédures en vigueur le {date_du_jour}. Si aucune information à jour n’est disponible, indiquez-le.A Contextual Filter verifies after generation that every cited reference has an active metadata tag. In case of doubt, the response is truncated and a warning message is added.
2.4 Validation Engine
- Business rules – for example: "The maximum reporting timeframe must not exceed 12h".
- Rules engine (Drools, Open Policy Agent) compares the generated text against constraints.
- In the event of non-compliance, the response is rejected or sent back for human review.
2.5 Knowledge Lifecycle Management
- Versioning Service – each procedure update creates a new immutable version (Git-like).
- Approval workflow – business owners validate the version before it is promoted to active status.
- Automated deprecation – previous versions are marked as obsolete as soon as a new version is published.
3. Complementary methods to ensure currency
3.1 Continuous Fine-tuning (Continual Learning)
Periodically training the model on a corpus of validated documents (e.g., the latest versions of procedures) allows weights to be adjusted towards recent information. This approach must be governed as follows:
- Strict selection – only certified, current documents are included.
- Rigorous evaluation – temporal precision metrics (P@k on a validation set containing previous vs current versions).
3.2 Use of a “retriever-only” LLM
In certain contexts, free generation can be disabled to retain only the relevant passages via the RAG component: the user sees the source text (e.g., an extract from the official manual) rather than a paraphrase. This eliminates any versioning hallucinations.
3.3 Post-deployment monitoring
- Interaction logs – capturing queries and responses, associating them with the used version metadata.
- Divergence alerts – triggering an alert when a response mentions a term absent from current sources.
- User feedback – a “Is this procedure up to date?” button to enrich the training set.
4. Realistic use case: updating business continuity procedures within a banking group
Context
An international bank must comply with the requirements of the European Digital Operational Resilience Act (DORA), which mandates a quarterly review of continuity plans. The incident management department uses an AI assistant to quickly retrieve the steps to follow in the event of a critical incident.
Deployment
- Ingestion – SOPs (Standard Operating Procedures) are stored in Confluence, with each version tagged with the DORA approval date.
- Indexing – A CI/CD pipeline extracts the content, adds metadata (status: active, valid_until: 2024‑06‑30), and creates embeddings.
- RAG – The search service only returns SOPs where valid_until ≥ today.
- Prompt – The system includes the temporal filter in every LLM call.
- Validation – An OPA engine verifies that the indicated failover time does not exceed 30 minutes, in accordance with DORA.
Result
During an incident simulation test, the assistant suggests the current procedure (version dated 12 March 2024) and explicitly flags that the previous version from 15 November 2023 has been deprecated. No incidents are caused by obsolete procedures, and the average response time is reduced from 45s to 12s.
Lessons Learned
- Temporal filtering prevents anachronistic responses.
- Business validation ensures regulatory compliance prior to dissemination.
- Operator feedback enables dataset enrichment and continuous model improvement.
5. Risks, limitations and points of vigilance
Points of vigilance
| Domain | Risk | Mitigation |
|---|---|---|
| Source quality | Unofficial documents or unapproved versions integrated into the index. | Ingestion process with manual validation and digital signatures. |
| Filter temporality | Discrepancy between system date and actual validity date (e.g. time zones). | Use a reliable NTP time server and store dates in UTC. |
| LLM hallucination | The model adds details not present in the retrieved sources. | “Retriever-only” mode or human post-editing is mandatory for critical responses. |
| Pipeline complexity | Increased latency (RAG queries + validation). | Intelligent caching of frequent results, parallelisation of the rules engine. |
| Management of multiple versions | Conflicts between several regulations (e.g. national vs European). | Prioritise jurisdiction metadata and apply a conflict resolution algorithm. |
| Infrastructure cost | Vector storage, regular fine-tuning, and rules engines consume resources. | Cost-benefit analysis, implementation of a dedicated AI/Governance budget. |
Technical limitations
- LLMs remain susceptible to statistical biases: even with a temporal filter, they may favour the most frequent phrasing within the corpus.
- RAG does not guarantee exhaustiveness; if a procedure is not indexed (e.g., a non-parsable PDF document), it will be absent from the response.
- Automated validation relies on hand-written rules: every new regulatory constraint requires an engineering effort.
6. Organisational decisions: what concrete actions should be taken?
For decision-makers (CIO, CISO, DPO)
- Establish AI governance – a committee including business, security, and compliance stakeholders to validate every update to the knowledge base.
- Deploy an automated ingestion pipeline with digital signatures for official documents to guarantee authenticity.
- Adopt the RAG model as the access layer for procedures; avoid 'on-the-fly' responses based solely on the LLM.
For technical teams
- Implement a vector database (e.g., Milvus) with temporal and jurisdictional metadata.
- Develop a rules engine (OPA, Drools) that executes post-generation to filter out non-compliant responses.
- Integrate interaction monitoring to rapidly detect version drift.
For business units
- Train users to formulate prompts that include date specifications ("procedure in effect as of 15 May 2024").
- Establish a systematic feedback process whenever a response appears questionable.
- Document discrepancies between the AI version and official documentation to enrich the corpus.
7. Recommended roadmap (12 months)
| Month | Key action | Owner |
|---|---|---|
| 1‑2 | Mapping of official sources (procedures, regulations) | IT Department / Business units |
| 3‑4 | Implementation of the ingestion pipeline + temporal metadata | DevOps Team |
| 5‑6 | Vector database deployment and RAG integration | AI Architecture |
| 7‑8 | Construction of the validation engine (business rules) | CISO / Compliance |
| 9 | Pilot phase with a critical service (e.g. customer support) | Project Management |
| 10‑11 | Log analysis, adjustment of freshness filters and prompts | Data Science |
| 12 | Final validation, documentation and user training | AI Governance Committee |
Operational conclusion
Language models provide a natural interface for accessing business procedures; however, without a governance framework and technical time-verification mechanisms, they risk disseminating outdated information. By combining:
- the temporal indexing of official sources,
- date-filtered retrieval-augmented generation,
- automated validation based on business rules,
- and a continuous ingestion and feedback process,
organisations can transform this risk into an opportunity: AI becomes not a substitute, but a certified assistant that always returns the most recent version of procedures. The key lies in the discipline of the knowledge lifecycle and the joint involvement of business, security and technical teams.
Key takeaways for decision-makers
| Point | Concrete action |
|---|---|
| Governance | Establish an AI/Compliance committee responsible for validating every version of the procedures. |
| Infrastructure | Deploy a vector database with temporal metadata and a RAG engine. |
| Validation | Implement a rules engine that rejects or alerts on non-compliant responses. |
| Feedback | Set up a user feedback system to enrich the corpus. |
| Training | Educate users on formulating queries that include the desired effective date. |
References
[1] OpenAI, « Embedding models », 2023, https://platform.openai.com/docs/guides/embeddings, accessed 22 July 2026. [2] Lewis, M., et al., « Retrieval‑Augmented Generation for Knowledge‑Intensive NLP Tasks », Proceedings of the 2020 Conference on Empirical Methods in Natural Language Processing, 2020, https://aclanthology.org/2020.emnlp-main.689.pdf, accessed 20 July 2026. [3] NIST, « AI Risk Management Framework (AI RMF) », Version 1.0, August 2023, https://www.nist.gov/artificial-intelligence/ai-risk-management-framework, accessed 21 July 2026. [4] ISO/IEC 42001, « Information technology — Artificial intelligence — Governance of AI », 2024, https://www.iso.org/standard/79595.html, accessed 22 July 2026. [5] ANSSI, « Guide de bonnes pratiques pour la mise en œuvre d’assistants IA dans les organisations », 2022, https://www